Tenure One · 2025–2026
Viveka 1.0
Mechanistic interpretability of large language models - probing the internal circuits behind hallucinations, factual recall, and in-context learning.
Technical Introduction
Hallucinations
Non linear low- dimensional subspaces of truthfulness, truthflow ,
autoencoders
Factual Recall
Two Hop Circuits, Circuit Analysis
Toy models
Studying Transformers in framework of Hidden Markov Models
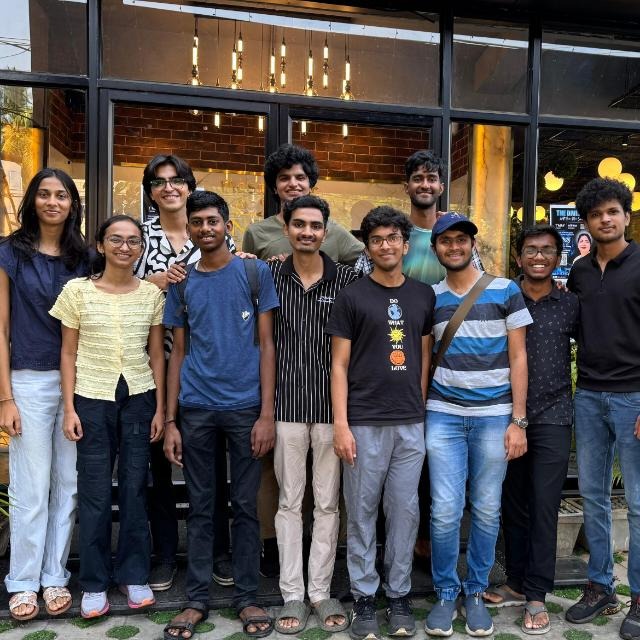
Meet the Viveka 1.0 Team
2 project leads and 9 researchers driving interpretability research through the 2025–26 academic year.
Blogs, papers & publications.
⊕
Through the Lenses: A Circuit Odyssey
📄 Blog Post
∇
Factual correctness representations are non linear and lie in low dimensional
subspaces.
Upcoming
⊕
Two Hop Factual Recall
Upcoming
λ
Toy models
Upcoming
Join Viveka 1.0
Recruitment for this tenure is over. Find the application below.